Optimizing the Output: Continuous Improvement for Generative AI Support
The launch of a generative AI support tool can feel like the finish line. Early results are often encouraging with improvements in response times, agents handling more interactions, and customers receiving faster answers. But after the initial gains, a familiar post-launch slump can emerge. As the system encounters new customer questions, unexpected phrasing, emerging products, policy changes, and increasingly complex edge cases, performance can plateau (or begin to decline). What worked during the first few weeks may not be enough to sustain quality at scale. Treating generative AI as a “set-it-and-forget-it” solution creates a slow accumulation of operational debt as knowledge bases become outdated, prompts lose effectiveness as use cases evolve, and previously unseen failure modes go unaddressed. Over time, these gaps can translate into inaccurate answers, unnecessary escalations, inconsistent experiences, and rising customer friction.
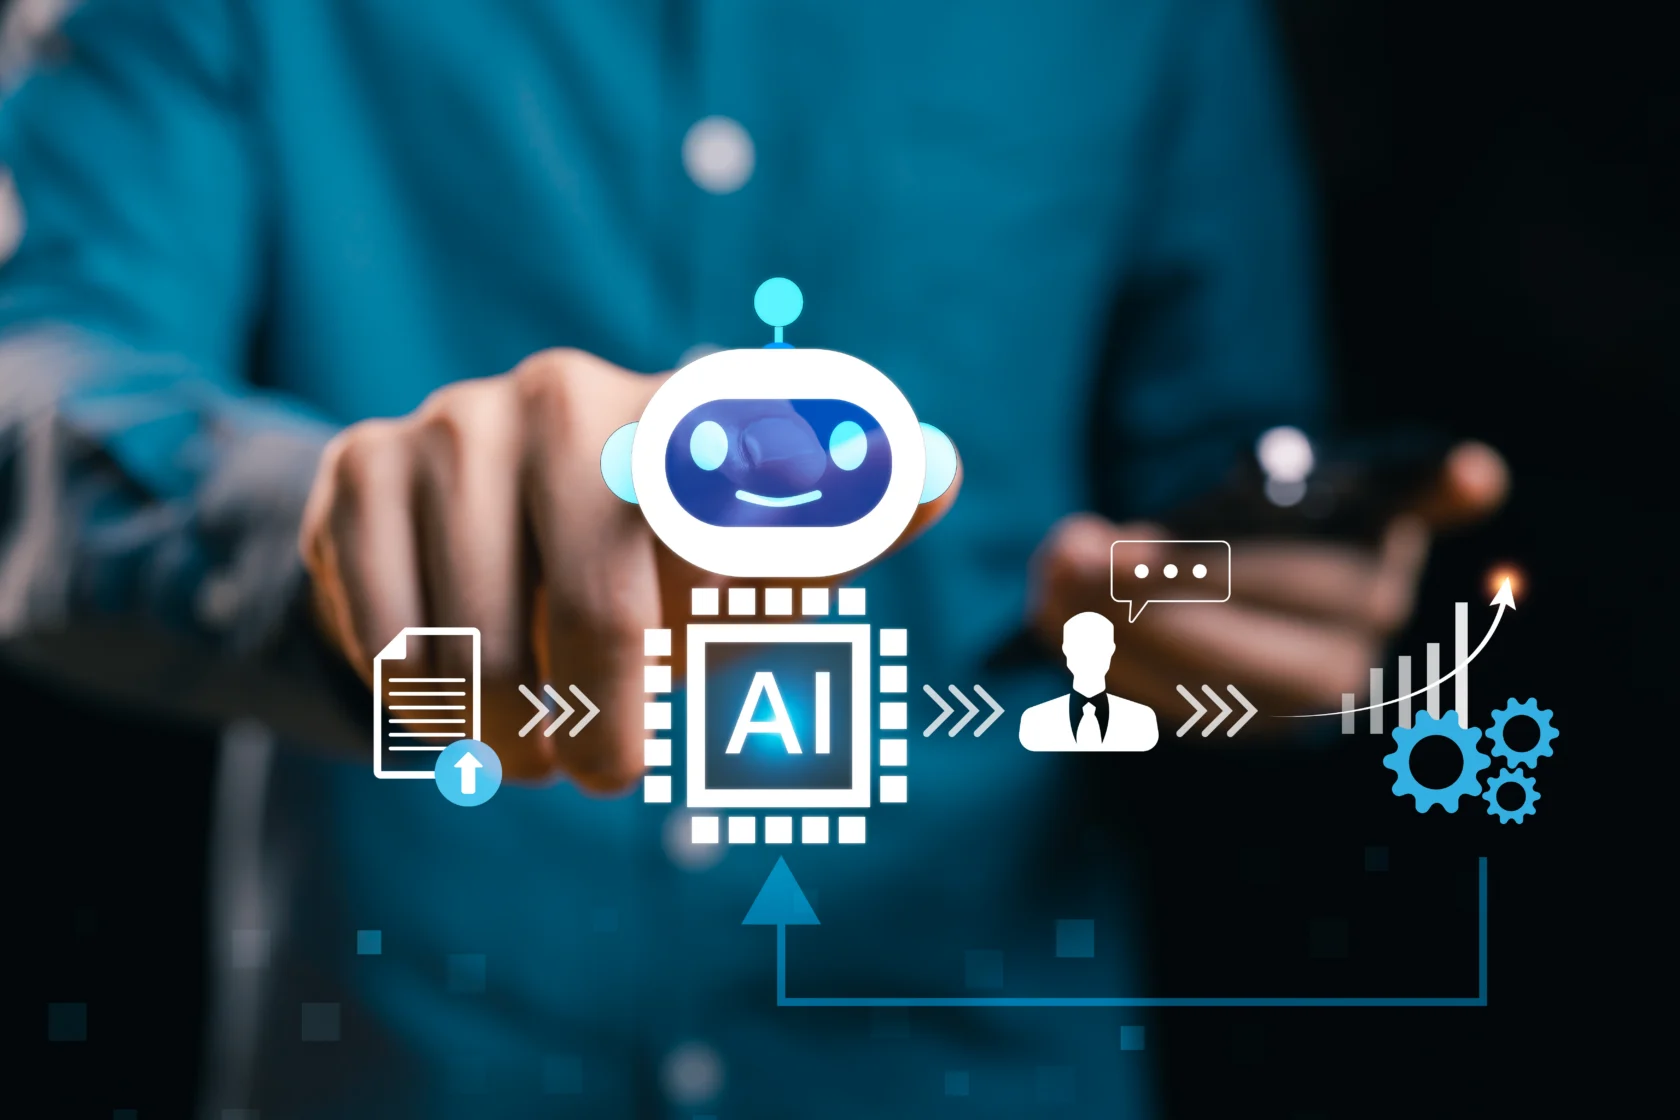
The answer is to shift from launch management to continuous AI optimization: an operational lifecycle built around measurement, learning, refinement, and scale. Rather than evaluating an AI support system solely on its initial performance, CX leaders and operational AI owners should establish ongoing mechanisms to audit interactions, identify emerging failure patterns, refresh knowledge inputs, test and tune system prompts, and measure the impact of every change. This creates a feedback loop in which real-world customer interactions become a source of insight, and those insights drive targeted improvements. The goal is to create a generative AI customer service operation that continually learns from experience, adapts to changing customer needs, and becomes more effective over time.
Establishing the Evaluation Engine
A sustainable generative AI support operation starts with an evaluation engine that measures more than how many interactions the system deflects from your human agents. Deflection can indicate efficiency, but it doesn’t reveal whether customers received the answer they were looking for or reached a resolution. CX teams should therefore track a balanced set of metrics, including factual accuracy, resolution efficacy, changes in customer sentiment, and model refusal rates. Together, these measures provide a clearer picture of whether AI is genuinely improving the customer experience. Evaluation should also combine automated monitoring with targeted human CX quality assurance. Real-time LLM-as-a-judge systems can continuously assess large volumes of interactions for issues such as relevance, accuracy, and adherence to guidelines which help teams identify trends quickly. Human reviewers remain essential for edge cases, ambiguous interactions, and low-confidence responses where automated evaluation may miss important context. Most importantly, continuous evaluation should create a feedback loop. Explicit signals such as CSAT scores and customer comments should be analyzed alongside implicit signals, including immediate agent overrides, repeated customer questions, escalations, and follow-up support tickets. Connecting these signals helps operational teams move beyond isolated failures to identify recurring knowledge gaps, prompt weaknesses, and workflow issues. The result? An evaluation framework that turns everyday customer interactions into actionable intelligence for continuous AI improvement.
Maintaining the Knowledge Foundation
Generative AI is only as reliable as the knowledge foundation it can access, making ongoing content governance a core part of continuous AI support optimization. Knowledge bases and vector databases should be routinely audited to identify and remove redundant, outdated, or conflicting documentation. Without this, retrieval systems can surface competing answers or irrelevant content which increase the risk of inaccurate responses and undermine customer trust. Teams should also treat failed AI interactions as valuable signals for strengthening the knowledge foundation. Reviewing unanswered questions, low-confidence responses, escalations, and repeated customer queries can reveal information blind spots that existing documentation doesn’t address. These patterns provide a data-driven roadmap for creating new help-center articles, expanding existing guidance, and prioritizing content updates based on actual customer demand.
Equally as important is how information is structured for large language models. Internal documentation should follow clear hierarchies, consistent terminology, concise formatting, and meaningful metadata so retrieval systems can identify and rank the most relevant content efficiently. Content should be organized into self-contained units rather than relying on context that may be difficult for an AI system to retrieve. By combining disciplined content pruning, gap analysis, and LLM-friendly information architecture, CX teams can turn their knowledge base from a static repository into a continuously maintained foundation for accurate, relevant, and dependable AI-powered support.
Iterative Prompting and Guardrail Engineering
Continuous improvement also requires treating system prompts and guardrails as living components rather than one-time configurations. Teams should regularly refine role definitions, tone directives, response structures, and output formatting rules based on patterns identified through real-world conversation analytics. For example, recurring misunderstandings may indicate that the AI needs clearer instructions about its role, while inconsistent response formats may call for more explicit output requirements. Prompt tuning outputs should then pass through a structured regression testing process. Before deployment, updated prompts can be tested against historical conversation datasets containing both successful interactions and known failure cases. This helps teams determine whether a change resolves the targeted issue without introducing new errors, such as reduced accuracy, inappropriate refusals, or degraded performance in unrelated scenarios.
Human-agent collaboration provides another critical feedback loop. Frontline support teams interact with AI-generated summaries and suggested responses every day, giving them a practical perspective on where the technology succeeds and where it creates additional work. Capturing agent feedback through structured annotations, override reasons, and recurring issue reports can reveal prompt weaknesses that automated evaluations overlook. By combining conversation analytics, regression testing, and frontline feedback, organizations can systematically evolve prompts and guardrails while preserving reliability. This creates an iterative optimization process in which every improvement is tested, measured, and informed by the people closest to customer interactions.
Learn More at Nashville Customer Contact Week
The true value of generative AI customer service is through disciplined, ongoing iteration and quality control. Organizations that build structured, continuous improvement processes will outpace competitors by delivering increasingly accurate, empathetic, and efficient automated support experiences.
Want to learn more? Register now for Nashville Customer Contact Week. Happening from Wednesday, October 7 through Friday, October 9, 2026, the Nashville schedule is packed with creative panels, networking events, and inspiring speakers who are leaders from across the customer contact sector.
This is where customer experience professionals come to solve real challenges and shape the future of service. Invest in your development, spark transformation within the organization, and walk away with a renewed vision for what’s possible in customer experience. We can’t wait to see you there this summer. Questions? Reach out to our team.